
Moonshot AI launched Kimi K3.1 Pro, "our most capable 3T-class open-weight model": a multimodal mixture-of-experts with 2.8T total and 104B active parameters and a 1M-token context window. It is live on Kimi.ai, Kimi Work, Kimi Code and the Kimi API (platform.kimi.ai), alongside K3.1 Pro Highspeed, which is 2 to 3x faster. Open weights are promised by November 4, 2026. The tech blog has the details. It follows Kimi K3, whose weights shipped 11 days after its July launch, and keeps K3's 2.8T / 104B-active size.
What Moonshot is claiming
- Full-project coding: games in Unreal, Unity and Godot.
- 3D modeling: parametric 3D modeling in Blender and CAD.
- Finance: "more reliable at finance work," with accurate modeling and hallucination down by 65%.
- Overall: "matching the strongest proprietary models across coding, agentic and knowledge benchmarks."
The benchmark chart
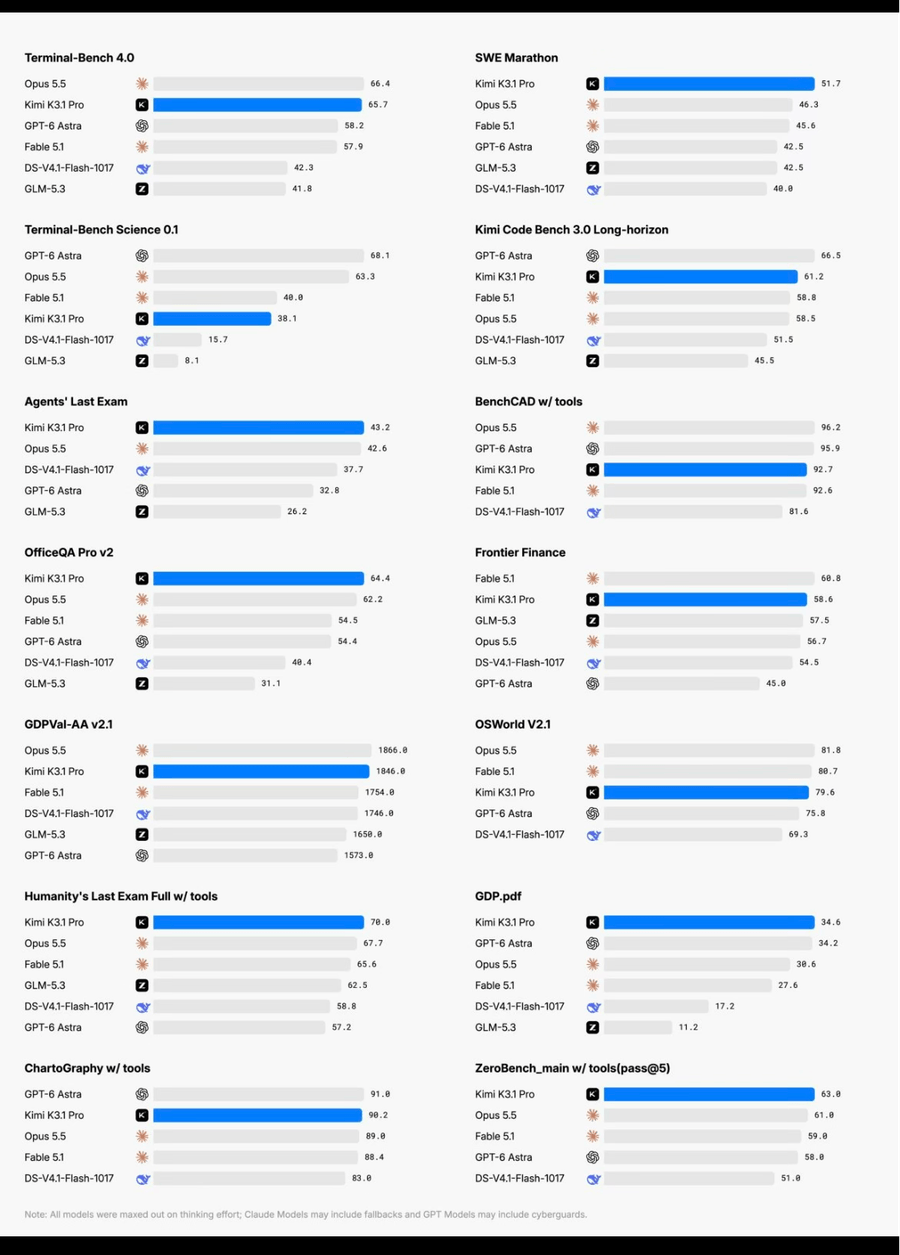 Moonshot's benchmark chart, from the Kimi K3.1 Pro announcement. All models were maxed out on thinking effort; Claude models may include fallbacks and GPT models may include cyberguards.
| Benchmark | Kimi K3.1 Pro | Opus 5.5 | Fable 5.1 | GPT-6 Astra |
|---|---|---|---|---|
| SWE Marathon | 51.7 | 46.3 | 45.6 | 42.5 |
| Humanity's Last Exam, full, with tools | 70.0 | 67.7 | 65.6 | 57.2 |
| OfficeQA Pro v2 | 64.4 | 62.2 | 54.5 | 54.4 |
| Agents' Last Exam | 43.2 | 42.6 | — | 32.8 |
| GDP.pdf | 34.6 | 30.6 | 27.6 | 34.2 |
| ZeroBench (pass@5, with tools) | 63.0 | 61.0 | 59.0 | 58.0 |
| Terminal-Bench 4.0 | 65.7 | 66.4 | 57.9 | 58.2 |
| GDPVal-AA v2.1 (Elo) | 1846 | 1866 | 1754 | 1573 |
| ChartoGraphy, with tools | 90.2 | 89.0 | 88.4 | 91.0 |
| Kimi Code Bench 3.0 long-horizon | 61.2 | 58.5 | 58.8 | 66.5 |
| Frontier Finance | 58.6 | 56.7 | 60.8 | 45.0 |
| OSWorld V2.1 | 79.6 | 81.8 | 80.7 | 75.8 |
| BenchCAD, with tools | 92.7 | 96.2 | 92.6 | 95.9 |
| Terminal-Bench Science 0.1 | 38.1 | 63.3 | 40.0 | 68.1 |
Tallied from the chart, Kimi K3.1 Pro is first on 6 of 14 benchmarks, top two on 11 and top three on 13. Head to head, it beats Opus 5.5 on 9 of 14 rows, GPT-6 Astra on 10 of 14 and Fable 5.1 on 10 of 13 (Fable has no Agents' Last Exam bar). The margins on the wins are small: 0.6 points on Agents' Last Exam, 0.4 on GDP.pdf against GPT-6 Astra, 2.3 on Humanity's Last Exam against Opus 5.5. It trails Opus 5.5 by 0.7 on Terminal-Bench 4.0 and 20 Elo on GDPVal-AA.
The one clear weakness is Terminal-Bench Science, where it scores 38.1 against 68.1 for GPT-6 Astra and 63.3 for Opus 5.5, fourth of six. The two other models in the chart, DeepSeek's V4.1 Flash (1017 snapshot) and GLM-5.3, trail Kimi on every row they appear in (14 and 10 rows). One of the benchmarks, Kimi Code Bench 3.0, is Moonshot's own. See also coverage of Opus 5.5, Fable 5.1, GPT-6 Astra and DeepSeek V4.1 Flash.
The Artificial Analysis Intelligence Index
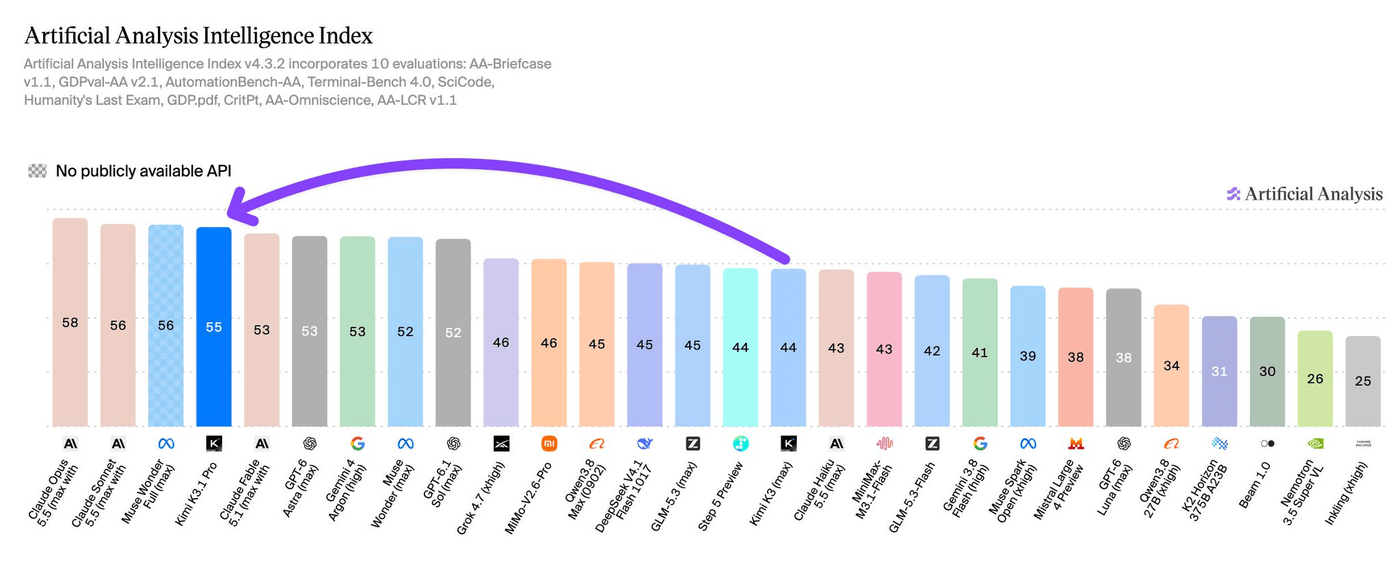 Artificial Analysis Intelligence Index v4.3.2, which averages 10 evaluations: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience and AA-LCR v1.1.
Artificial Analysis's index, run by a third party rather than Moonshot, puts Kimi K3.1 Pro at 55, 11 points above Kimi K3 (44, at max effort) and fourth of the 28 models charted. Only Claude Opus 5.5 (58), Claude Sonnet 5.5 (56) and Meta's Muse Wonder Full (56, shown without a public API) score higher. It is ahead of Claude Fable 5.1, GPT-6 Astra and Gemini 4 Argon (all 53), and of GPT-6.1 Sol and Muse Wonder (52). Among models with a public API it is third, within three points of the top.
Moonshot's weights, once released on November 4, would sit well clear of the open-weight field in this chart: 9 points above MiMo-V2.6-Pro (46), 10 above DeepSeek V4.1 Flash 1017 (45) and 16 above Muse Spark Open (39). The index's overlap with Moonshot's own chart (GDPval-AA, Terminal-Bench 4.0, Humanity's Last Exam and GDP.pdf) is where Kimi is strongest, while a weak showing on Terminal-Bench Science does not feed into it.