
Mark Zuckerberg introduced Muse Wonder as "our new family of frontier models with state of the art performance for personal and professional agentic work." Meta's Alexandr Wang called it "the best model in the world for personal agents and professional agents," adding that Meta evaluated it against the best models in the world across agentic and coding tasks and "we think you all will like it." The family has two variants, Muse Wonder Full and Muse Wonder.
The benchmarks
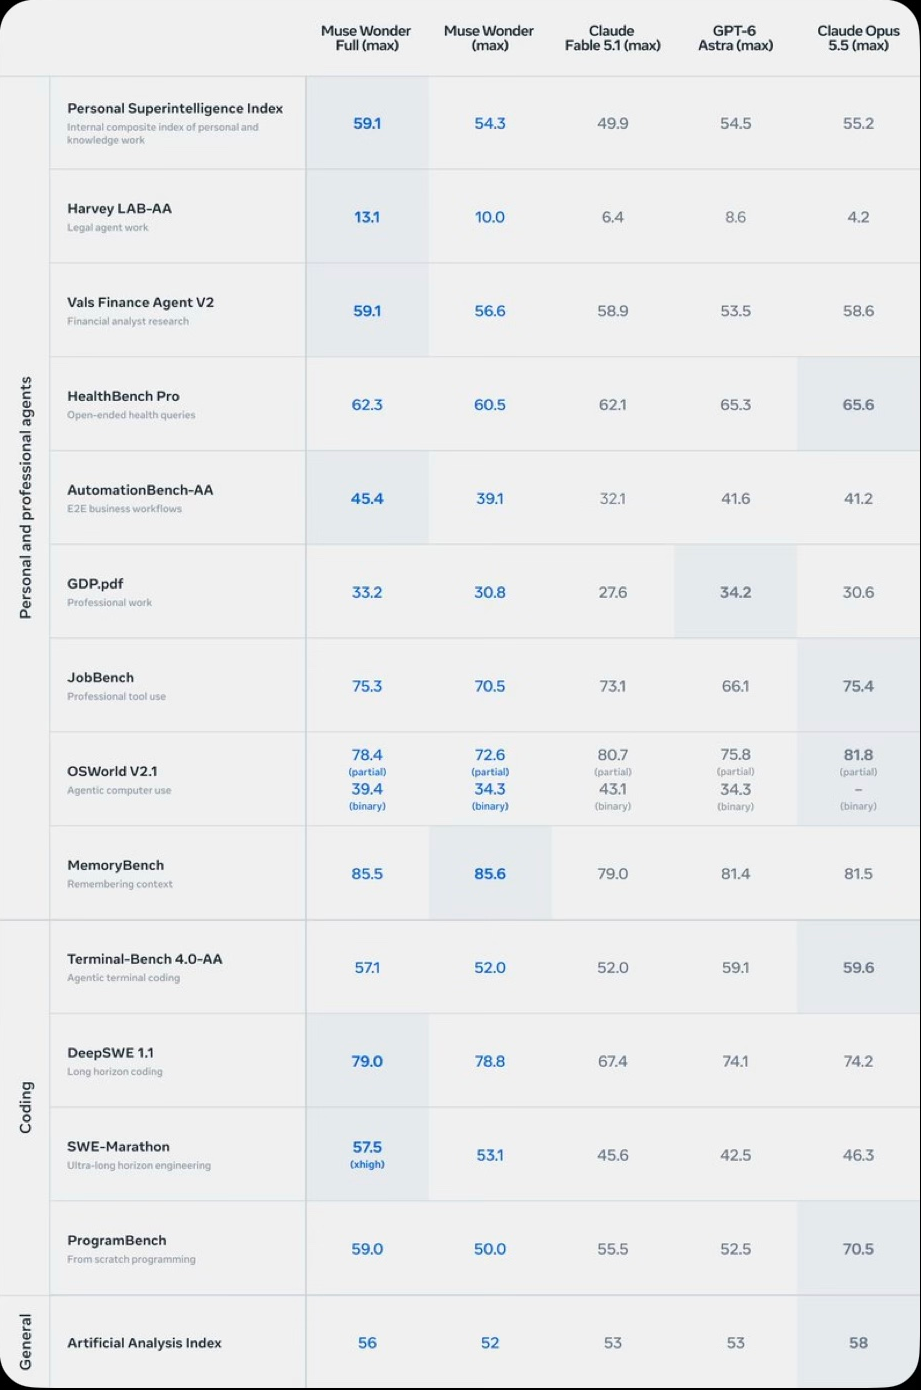 From Mark Zuckerberg's announcement.
Every model runs at its highest effort setting (max), except Muse Wonder Full on SWE-Marathon, which runs at xhigh. The best score in each row is in bold.
| Group | Benchmark | Muse Wonder Full | Muse Wonder | Claude Opus 5.5 | GPT-6 Astra | Claude Fable 5.1 |
|---|---|---|---|---|---|---|
| Personal and professional agents | Personal Superintelligence Index | 59.1 | 54.3 | 55.2 | 54.5 | 49.9 |
| Personal and professional agents | Harvey LAB-AA (legal agent work) | 13.1 | 10.0 | 4.2 | 8.6 | 6.4 |
| Personal and professional agents | Vals Finance Agent V2 (financial analyst research) | 59.1 | 56.6 | 58.6 | 53.5 | 58.9 |
| Personal and professional agents | HealthBench Pro (open-ended health queries) | 62.3 | 60.5 | 65.6 | 65.3 | 62.1 |
| Personal and professional agents | AutomationBench-AA (end-to-end business workflows) | 45.4 | 39.1 | 41.2 | 41.6 | 32.1 |
| Personal and professional agents | GDP.pdf (professional work) | 33.2 | 30.8 | 30.6 | 34.2 | 27.6 |
| Personal and professional agents | JobBench (professional tool use) | 75.3 | 70.5 | 75.4 | 66.1 | 73.1 |
| Personal and professional agents | OSWorld V2.1 (agentic computer use), partial | 78.4 | 72.6 | 81.8 | 75.8 | 80.7 |
| Personal and professional agents | OSWorld V2.1, binary | 39.4 | 34.3 | – | 34.3 | 43.1 |
| Personal and professional agents | MemoryBench (remembering context) | 85.5 | 85.6 | 81.5 | 81.4 | 79.0 |
| Coding | Terminal-Bench 4.0-AA (agentic terminal coding) | 57.1 | 52.0 | 59.6 | 59.1 | 52.0 |
| Coding | DeepSWE 1.1 (long-horizon coding) | 79.0 | 78.8 | 74.2 | 74.1 | 67.4 |
| Coding | SWE-Marathon (ultra-long-horizon engineering) | 57.5 | 53.1 | 46.3 | 42.5 | 45.6 |
| Coding | ProgramBench (from-scratch programming) | 59.0 | 50.0 | 70.5 | 52.5 | 55.5 |
| General | Artificial Analysis Index | 56 | 52 | 58 | 53 | 53 |
Counting OSWorld V2.1 once, on partial credit, a Muse Wonder model has the top score in 7 of the 14 rows: Muse Wonder Full in six and Muse Wonder in MemoryBench. Claude Opus 5.5 leads six, GPT-6 Astra one, and Claude Fable 5.1 none, although it posts the best OSWorld binary figure (43.1).
Muse Wonder Full's widest leads are on SWE-Marathon (+11.2 over Opus 5.5, at a lower effort setting than the rivals' max), DeepSWE (+4.8 over Opus 5.5), Harvey LAB-AA (+4.5 over Astra), the Personal Superintelligence Index (+3.9 over Opus 5.5) and AutomationBench-AA (+3.8 over Astra). On Vals Finance Agent V2 it edges Fable 5.1 by 0.2. The Index is described as an internal composite index of personal and knowledge work.
Opus 5.5 leads Full on ProgramBench by 11.5 (70.5 against 59.0), OSWorld V2.1 partial credit by 3.4, HealthBench Pro by 3.3, Terminal-Bench 4.0-AA by 2.5, the Artificial Analysis Index by 2 points (58 against 56) and JobBench by 0.1. Astra leads Full on GDP.pdf by 1.0. The pattern is that Full leads on long-horizon coding and on agent and knowledge-work rows, while Opus 5.5 holds from-scratch programming, computer use and health.
The rows span three groups: personal and professional agents (nine benchmarks, with OSWorld V2.1 scored two ways), coding (four) and general (one). Full scores above the standard Muse Wonder on 13 of the 14 rows. The standard Muse Wonder tops MemoryBench at 85.6, 0.1 above Full, and ranks second of the five on SWE-Marathon (53.1) and DeepSWE (78.8, 0.2 behind Full).
Context
Muse Wonder follows Muse Spark 1.3, Meta's previous model, released on September 3, and the Muse personal agent Meta launched on September 9.
The comparison models are Claude Opus 5.5, launched on September 22, and GPT-6 Astra, released on September 3, along with Claude Fable 5.1, which tops no row.