
Anthropic launched Claude Haiku 5.5, calling it "the cheapest, fastest, and most capable small model we've ever released." On average it costs around 75% less to run than Claude Haiku 4.5. It is the first Haiku with an adjustable effort setting, has a 1M-token context window (Haiku 4.5: 200K), and is available in the API as claude-haiku-5-5. Details come from the launch page.
Where it fits
Haiku 5.5 is built for high-volume, cost-sensitive work: repetitive tasks such as summaries and classification, and a subagent role alongside Claude Opus 5.5 and Sonnet 5.5 on coding. Anthropic also calls it fast enough for live customer support and browser use. The effort setting runs from low to max, defaults to medium, and adaptive thinking is on by default, so each task can be tuned for cost or for intelligence. Maximum output is 128K tokens.
Benchmarks
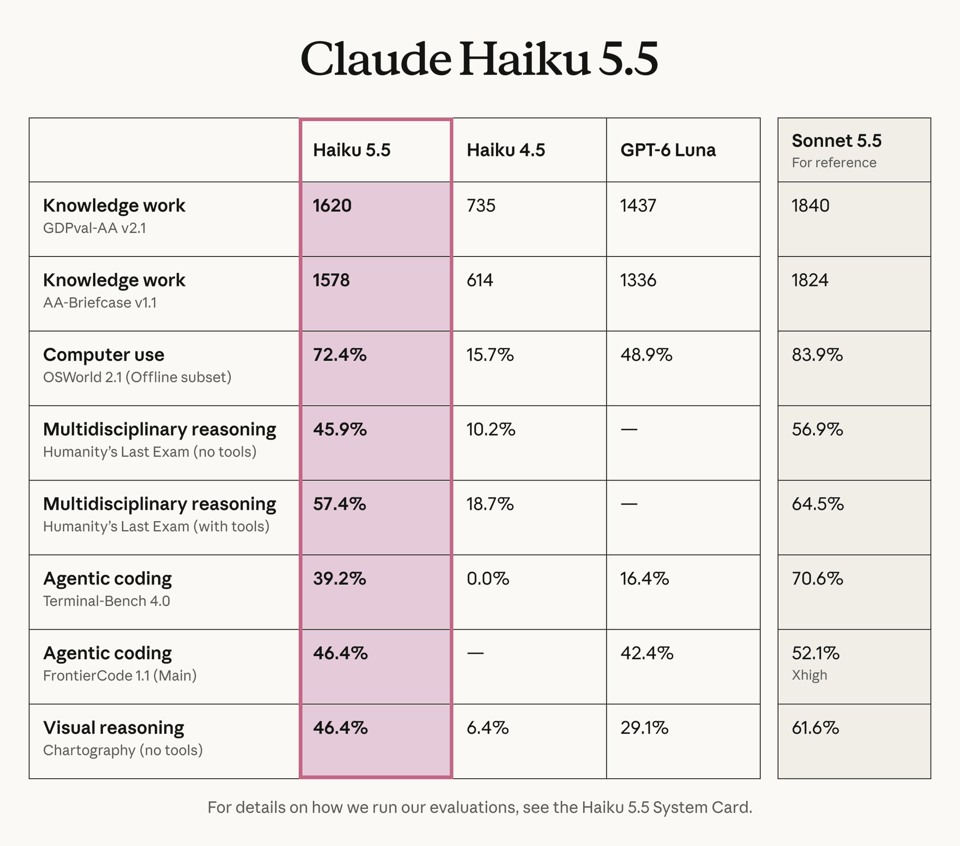 From Anthropic's launch page.
| Benchmark | Haiku 5.5 | Haiku 4.5 | GPT-6 Luna | Sonnet 5.5 |
|---|---|---|---|---|
| GDPval-AA v2.1 (Elo) | 1620 | 735 | 1437 | 1840 |
| AA-Briefcase v1.1 (Elo) | 1578 | 614 | 1336 | 1824 |
| OSWorld 2.1, offline subset | 72.4% | 15.7% | 48.9% | 83.9% |
| Humanity's Last Exam, no tools | 45.9% | 10.2% | — | 56.9% |
| Humanity's Last Exam, with tools | 57.4% | 18.7% | — | 64.5% |
| Terminal-Bench 4.0 | 39.2% | 0.0% | 16.4% | 70.6% |
| FrontierCode 1.1 (Main) | 46.4% | — | 42.4% | 52.1% (Xhigh) |
| Chartography, no tools | 46.4% | 6.4% | 29.1% | 61.6% |
Against Haiku 4.5, the jumps are large: OSWorld 4.6x (72.4% vs 15.7%), Humanity's Last Exam without tools 4.5x, Chartography 7.3x, and Terminal-Bench from 0.0% to 39.2%. On GDPval, Haiku 5.5 is 885 Elo ahead (1620 vs 735).
GPT-6 Luna, which has the same $0.10 / $0.50 price, appears on six rows and Haiku 5.5 leads on all six: GDPval 1620 vs 1437, AA-Briefcase 1578 vs 1336, OSWorld 72.4% vs 48.9%, Terminal-Bench 39.2% vs 16.4%, FrontierCode 46.4% vs 42.4%, and Chartography 46.4% vs 29.1%.
Sonnet 5.5, shown for reference, stays ahead everywhere. Haiku 5.5 reaches about 86% of its OSWorld score (72.4 of 83.9), 88% on GDPval, 87% on AA-Briefcase, 89% on FrontierCode (against Sonnet at Xhigh) and 89% on Humanity's Last Exam with tools. The weakest rows are Chartography (75%) and Terminal-Bench (56%).
Cost versus performance by effort level
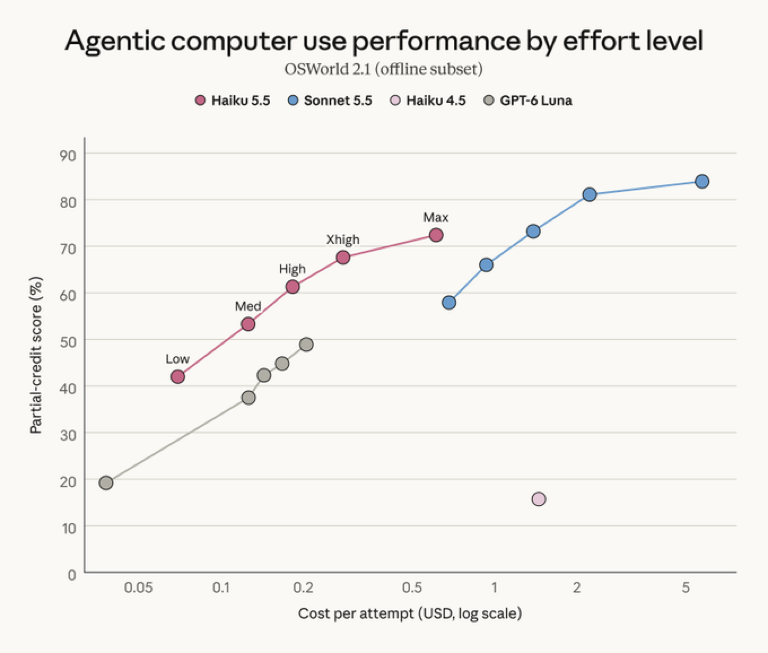 OSWorld 2.1 effort chart, from Anthropic's launch page.
On OSWorld, values read roughly off the log axis, Haiku 5.5 climbs from about 42% at low effort (about $0.07 per attempt) to about 53% at medium, 61% at high, 67.5% at xhigh and 72.4% at max (about $0.6). Sonnet 5.5's cheapest point is about 58% at about $0.7, so Haiku 5.5 at high effort (about $0.18) already exceeds it at roughly a quarter of the cost. Haiku 4.5 sits near 16% at about $1.5, so Haiku 5.5 at max scores 4.6x higher for roughly 2.5x less. Luna tops out near 49% at about $0.2, a level Haiku 5.5 passes at medium effort for about $0.12.
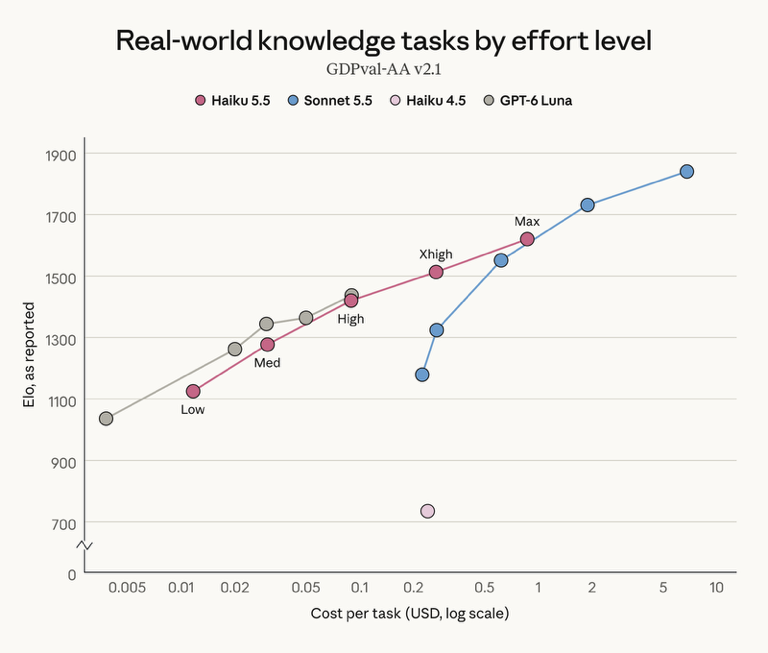 GDPval-AA effort chart, from Anthropic's launch page.
On GDPval-AA, Haiku 5.5 runs from about 1125 Elo at about $0.012 per task (low) to 1280 at $0.03 (medium), 1420 at $0.09 (high), 1515 at $0.28 (xhigh) and 1620 at about $0.85 (max). Luna's top point is about 1437 at about $0.09, essentially level with Haiku 5.5 at high effort. Sonnet 5.5 reaches about 1550 at about $0.6 and 1730 at about $1.9, so Haiku 5.5 max beats the former at a higher cost and trails the latter. Haiku 4.5 scores 735 at about $0.23, so even Haiku 5.5's low setting is about 390 Elo higher at one-nineteenth of the cost.
Pricing
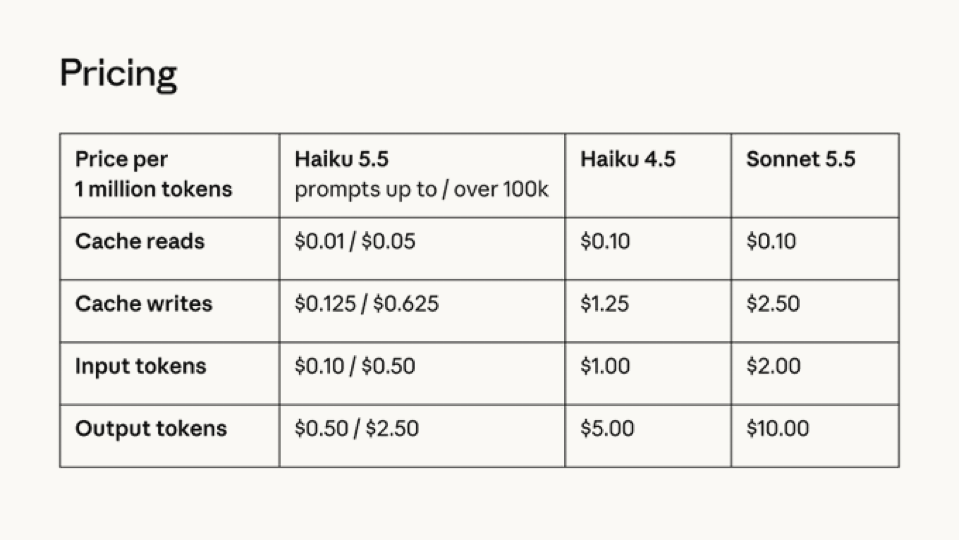 From Anthropic's launch page.
| Per million tokens | Haiku 5.5 (up to 100k / over 100k) | Haiku 4.5 | Sonnet 5.5 |
|---|---|---|---|
| Input | $0.10 / $0.50 | $1.00 | $2.00 |
| Output | $0.50 / $2.50 | $5.00 | $10.00 |
| Cache reads | $0.01 / $0.05 | $0.10 | $0.10 |
| Cache writes | $0.125 / $0.625 | $1.25 | $2.50 |
Per token, Haiku 5.5 is 10x cheaper than Haiku 4.5 on input, output, cache reads and cache writes, and 20x cheaper than Sonnet 5.5 on input and output ($0.10 vs $2.00 and $0.50 vs $10.00). Prompts over 100K tokens cost 5x more ($0.50 / $2.50).
The headline claim is smaller than the price list: a 90% per-token cut but about 75% less to run on average. If both hold, a typical task uses roughly 2.5x as many tokens on Haiku 5.5 as on Haiku 4.5, which would fit more thinking per task at the default medium effort.
Context
Haiku 5.5 follows Sonnet 5.5 and Opus 5.5 in the 5.5 family, and arrives as the low end of the price ladder ($0.10 / $0.50, against $2 / $10 and $4 / $20). Its closest price match is GPT-6 Luna, while DeepSeek V4.1 Flash is another cheap model this blog has covered.