
Nanbeige announced Nanbeige4.3-33B, saying it "delivers SOTA agentic performance among open models at ~30B parameters," with a base model released alongside it. Nanbeige is the LLM team at BOSS Zhipin. Coverage reports 33.1B parameters, a 512K-token context window and an Apache 2.0 license.
Teacher first
To "push the performance ceiling of small agents," Nanbeige says its strategy for the 4.3 series starts with "building a powerful teacher first." The 33B model is that teacher: it will be used to train upcoming smaller Nanbeige models, starting with Nanbeige4.3-3B. That is the same recipe Meta used for Muse Glimmer, which was distilled from the closed Muse Spark. Nanbeige reports strong results on agentic coding and cowork benchmarks, and says that when integrated into mainstream agent harnesses it tackles real-world tasks with cost-efficient inference.
The benchmarks
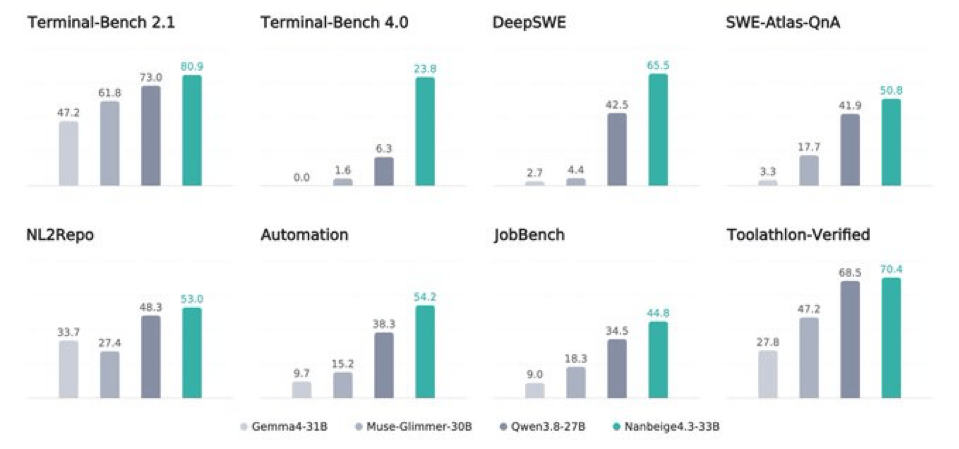 Benchmark comparison from Nanbeige's announcement.
| Benchmark | Nanbeige4.3-33B | Qwen3.8-27B | Muse Glimmer 30B | Gemma 4 31B |
|---|---|---|---|---|
| Terminal-Bench 2.1 | 80.9 | 73.0 | 61.8 | 47.2 |
| Terminal-Bench 4.0 | 23.8 | 6.3 | 1.6 | 0.0 |
| DeepSWE | 65.5 | 42.5 | 4.4 | 2.7 |
| SWE-Atlas-QnA | 50.8 | 41.9 | 17.7 | 3.3 |
| NL2Repo | 53.0 | 48.3 | 27.4 | 33.7 |
| Automation | 54.2 | 38.3 | 15.2 | 9.7 |
| JobBench | 44.8 | 34.5 | 18.3 | 9.0 |
| Toolathlon-Verified | 70.4 | 68.5 | 47.2 | 27.8 |
Nanbeige leads all eight rows, and the mean of the eight scores is 55.4 against 44.2 for Qwen3.8-27B, 24.2 for Muse Glimmer and 16.7 for Gemma 4. The margins over Qwen3.8-27B are narrow on Toolathlon-Verified (1.9 points) and NL2Repo (4.7) and wide on the hardest agentic rows: Terminal-Bench 4.0 is 3.8x higher (23.8 against 6.3), DeepSWE is 23 points ahead and Automation 15.9 points ahead. On Terminal-Bench 4.0 the two other rivals score near zero, so that row shows a real gap in long-horizon terminal work, not only a lead on rows where everyone does well. The chart is Nanbeige's own and coverage notes no third party has repeated the numbers, and community reaction on Chinese forums questioned whether the results were tuned to the benchmarks. For another fast local coding model this month, see Recursive's Flint.